OrcaRouter
One OpenAI-compatible AI gateway for production AI — adaptive routing, load balancing, guardrails, agent firewall, observability and governance across 200+ models.
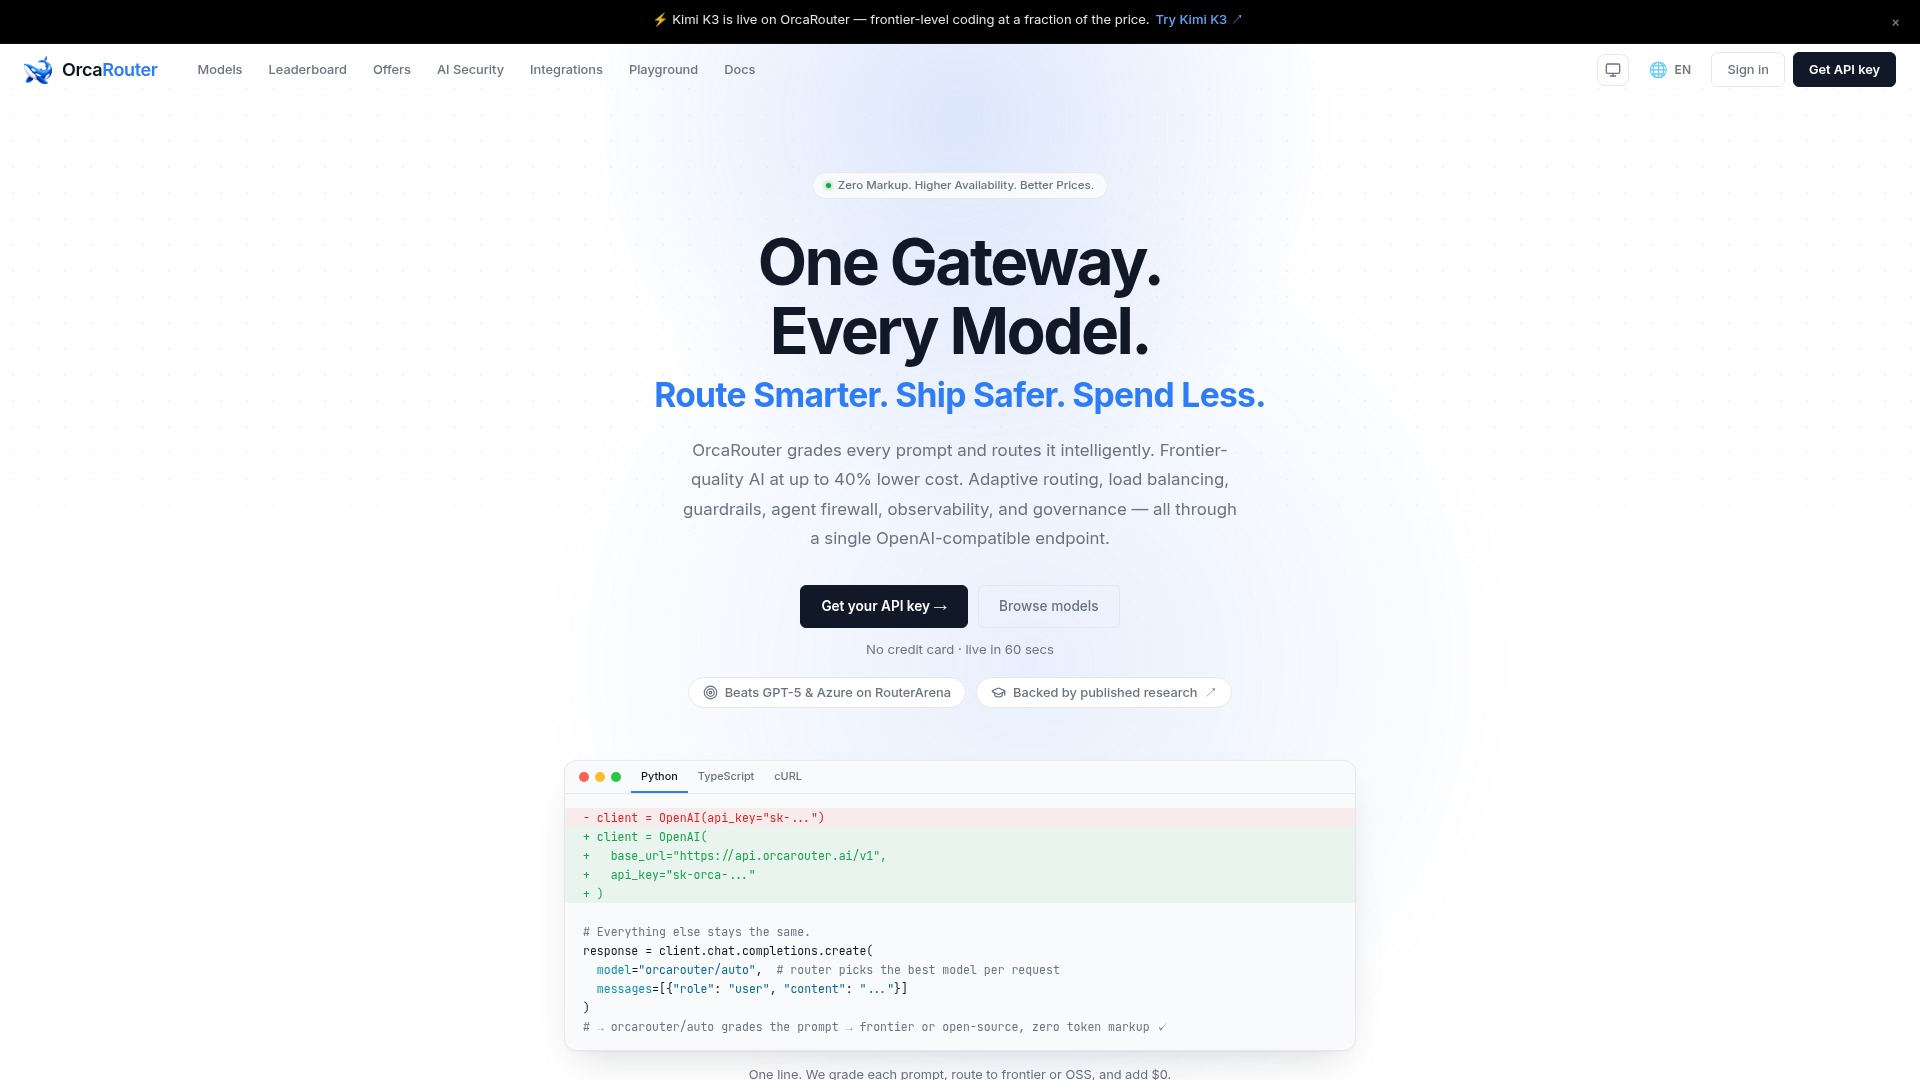
What is OrcaRouter?
OrcaRouter is an OpenAI-compatible AI gateway that gives you one endpoint to 200+ models, grading each prompt and routing it to the model that answers it best. It adds guardrails, an agent firewall, observability and governance on the same hop, for teams running AI in production. It charges no markup on tokens and does not log prompts unless logging is turned on.
Key features
- Adaptive routing
- every prompt is graded in under 1 ms and routed to a frontier or open-source model, with 75.5% accuracy reported on the public RouterArena leaderboard.
- Zero token markup
- OrcaRouter bills each provider's published rate and adds $0 per token, and it supports bringing your own provider keys.
- Guardrails
- PII, secrets, jailbreaks and prompt injection are stopped before the model sees them and before they are billed; pattern rules are free, and an AI-judge rule bills only its own check.
- Agent firewall
- every tool and MCP call is allowed, sent to a person for review, or blocked before it runs, with a human approval queue.
- Privacy controls
- data cloaking swaps names, emails and card numbers for stand-ins before they reach the model, logging is off by default, and retained logs can be sealed with hybrid post-quantum encryption (ML-KEM-768 + X25519) via the open-source SCUTTLE code.
- Observability and prompt management
- live spend, a per-prompt receipt, prompt versioning and reuse of cached calls without touching code.
- Compliance packs
- one policy per regulation, mapped to 32 frameworks including HIPAA, GDPR, SOC 2, the EU AI Act, OWASP and ISO 42001.
How to use OrcaRouter
- Get an API key from the OrcaRouter registration page — no credit card is required and setup is described as taking about 60 seconds.
- Point your SDK at the gateway: set
base_urltohttps://api.orcarouter.ai/v1and swap in your OrcaRouter API key. Existing OpenAI, Anthropic or Google SDK code keeps working. - Send requests with
model="orcarouter/auto"to let OrcaRouter grade and route each prompt, or name a specific model from the catalogue. - Turn on the controls your workload needs: guardrails, the agent firewall, data cloaking, zero-retention logging, post-quantum log sealing or a data region.
- Watch live spend and per-prompt receipts in the dashboard, and version prompts or reuse cached calls as needed.
Use cases
- Teams running production AI that want a single endpoint instead of maintaining separate provider integrations.
- Cost-sensitive applications: the site reports 150%+ inference cost savings with cache-aware adaptive routing.
- Agent builders who need every tool and MCP call graded, with risky calls routed to a human approval queue.
- Regulated teams that must map controls to HIPAA, GDPR, SOC 2, the EU AI Act or ISO 42001.
- Organisations that want to bring their own provider keys and keep prompt bodies unlogged by default.
Pricing
- Hacker
- Free forever, with zero markup on all tokens, routing across 200+ models with auto-failover, a basic dashboard, prompt versioning and 10 API keys.
- Team
- $499/mo, still zero markup. Includes everything in Hacker, up to 10 team seats, compliance enforcement and reports, unlimited API keys and priority support.
- Enterprise
- Custom pricing. Includes everything in Team, unlimited team seats, priority access to new models, every hidden and beta feature, dedicated infrastructure, a 99.99% uptime SLA and dedicated support.
Tokens are paid for in three ways: pay-as-you-go top-ups, a credit subscription that refills the wallet each period, or bringing your own provider keys. Top-ups and subscriptions bill at provider price with $0 added per token.
FAQ
Is OrcaRouter free to use?
Yes, the Hacker plan is free forever and carries zero markup on tokens. Team features cost $499/mo, and Enterprise pricing is custom.
Does OrcaRouter store or train on my prompts?
OrcaRouter never trains on prompts, and prompt and response bodies are not logged unless logging is turned on for the workspace. Request metadata such as time, model, tokens, cost and IP is kept for billing and security, and a zero-retention agreement locks body logging off.
Which models and SDKs does OrcaRouter support?
OrcaRouter routes across 200+ models from providers including OpenAI, Anthropic, Google, Qwen, DeepSeek, Grok, Kimi and MiniMax. It works with Python, TypeScript and cURL, and existing OpenAI, Anthropic or Google SDK code keeps working for Chat Completions, Responses, Embeddings, Images, Audio and streaming.
Does OrcaRouter add latency to requests?
Prompt grading takes under 1 ms and total added latency stays under 50 ms, according to the site. Cached prompt tokens and faster providers often win that time back.
How does OrcaRouter handle a provider outage?
OrcaRouter retries against healthy fallback capacity for the same or an equivalent model before the response starts, so upstream outages do not surface to users.
Can I choose where my data is processed with OrcaRouter?
A workspace data-region setting covers US, EU, UK, Asia-Pacific or China and tags compliance reports with that region. The site states that this does not yet pin where data is stored or where inference runs — that is handled by the provider serving the model you pick.
OrcaRouter
One OpenAI-compatible AI gateway for production AI — adaptive routing, load balancing, guardrails, agent firewall, observability and governance across 200+ models.
 Express
 Google Tag Manager
 Node.js
Free AI anime and manga generator. Turn text into anime episodes, manga, comics, webtoons and comic shorts in any art style — no drawing or animation skills needed.
Translate image text across 70+ languages with our advanced AI Image Translator to help you better expand your products globally to various countries
Advertised Here
Reach thousands of visitors daily. Get your spot now!
Tools similar to OrcaRouter
Generate text with industry leading privacy, quality and cost. Realistic text generation is now possible
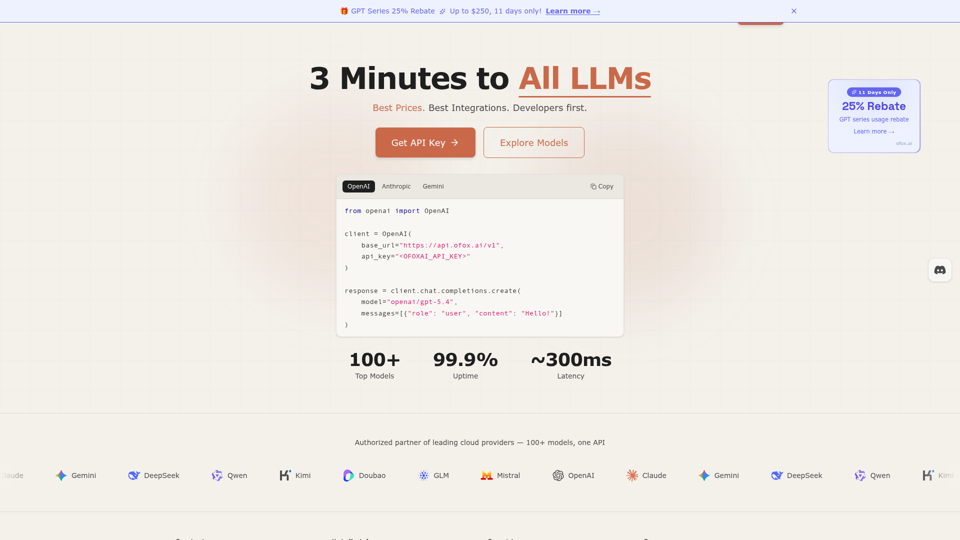
Unified LLM API gateway — access GPT-5.4, Claude Opus 4.6, Gemini 3.1, DeepSeek V3.2 and 100+ models through one API. OpenAI-compatible, 3-minute setup, pay-as-you-go. Low latency, 99.9% SLA. Built for developers who ship.
Better price, better stability. The unified LLM API gateway supporting OpenAI, Claude, Gemini, DeepSeek and 30+ providers.
HoneyHive is the AI observability and evals platform trusted by the Fortune 500. We help the world’s largest enterprises confidently scale agents in production with continuous evaluation and observability throughout the entire agent development lifecycle (ADLC), ensuring agents are trustworthy and reliable by design.
Access GPT, Claude, Gemini, Seedance, Kling & more via one EvoLink API. Get production-ready, cost-efficient access across LLM, image, and video models.
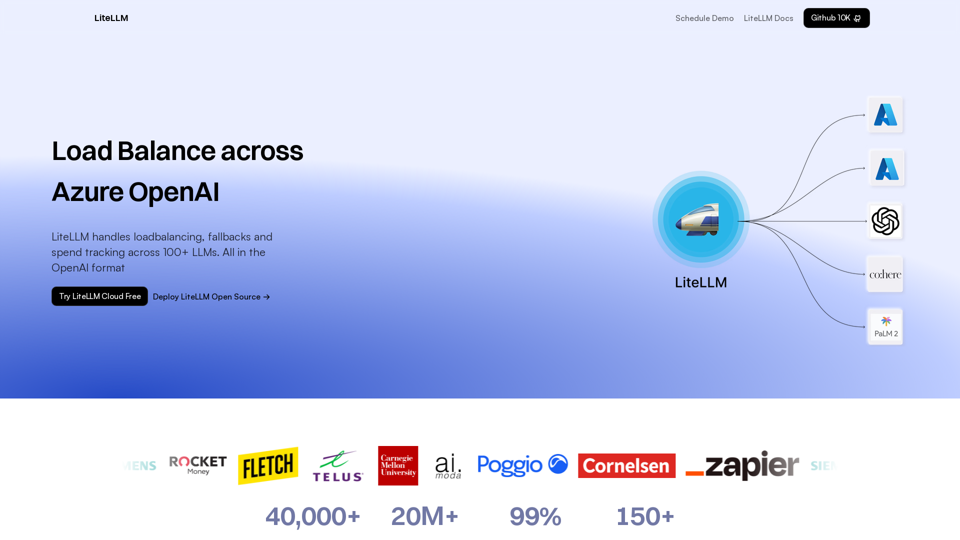
LiteLLM handles loadbalancing, fallbacks and spend tracking across 100+ LLMs. all in the OpenAI format

LiteLLM handles loadbalancing, fallbacks and spend tracking across 100+ LLMs. all in the OpenAI format
Explore image, video, and audio generation models in the SJolt playground, compare output quality and cost, then copy the same API request into production.